Northern Crown Bank is a large Schedule I Canadian bank serving approximately 14 million customers across Canada and United States. Like TD, RBC, and BMO, it maintains a mature, centralized GRC program with an established enterprise risk register, dedicated Privacy Office, and mature control environment.
However, even mature organizations must regularly apply full GRC rigor when undertaking major initiatives. The case study demonstrate how I would execute a complete end-to-end GRC process – from risk assessment through governance, controls, monitoring, and audit readiness – in response to such initiative: the launch of a new AI-powered digital banking platform that includes personalized financial insights, automated credit decisions, and open banking capabilities.
The scenario reflects real-world conditions in large Canadian banks, where GRC professionals are frequently called upon to assess significant changes, fill gaps in existing programs, integrate strong privacy protections, and provide clear risk-based recommendations to business stakeholders.
The same end-to-end framework used in the earlier OpenMRS healthcare clinic series is applied here, adapted to the scale, complexity, and regulatory intensity of a large financial institution, with strong emphasis on privacy integration throughout.
1. New AI-Powered Digital Banking Platform Features
The new platform includes the following capabilities:
AI-driven capabilities:
- Personalized Spending Recommendations: The AI analyzes transaction patterns and provides context-aware suggestions, such as “Based on your past three months of spending, you typically spend $1,200 on groceries and dining. We recommend setting aside $450 this month for upcoming rent and utilities to avoid overdraft fees.”
- Automated Credit Decisioning: Real time credit limit increases or small business loan approvals using machine learning models trained on transaction history, payment behavior, and external data sources.
- Real-time Fraud Detection: Use machine learning on transaction patterns to detect and flag suspicious activity instantly (e.g., unusual location or high-value purchases).
Enabling Capabilities:
- Open banking integration: Customer can securely share their banking data with trusted third-party apps, such as:
- Budget tools (e.g., Wealthsimple or YNAB-style apps)
- Investment Platforms (e.g., Wealthsimple or robo-advisors)
- Insurance comparison services
- Accounting software for small businesses
It uses a hybrid model development approach. Core credit decisioning and real-time fraud detection models are primarily developed and maintained internally by Northern Crown Bank’s data science and model risk management teams, although they may incorporate selected components or data services from specialized vendors. Personalization and recommendation engines are built using fine-tuned models derived from external foundation models, heavily customized with the Bank’s proprietary data and subject to internal security and bias controls. All models, regardless of origin, undergo the Bank’s internal validation, monitoring, and governance processes.
For this case study I treat that hybrid split as follows.
- Credit Decisions: The bank’s own model issues approve, refer, or decline. A vendor may supply credit-file data or calculated attributes (for exam Equifax or TransUnion). The vendor does not make the credit decision.
- Fraud: The bank’s own model decides whether to flag or hold a transaction. A vendor may supply an input signal such as device or behavior risk (for example LexisNexis ThreatMetrix or BioCatch).
- Recommendations: Fine-tuned foundation models, customized with bank’s data, as described above.
- Open banking: Third-party apps and APIs that receive only the data the customer authorized. This is not the credit model.
If a credit-file or feature call the bank model needs does not return in time, the application is referred or declined. It is not approved without a score.
This case study is inspired by real-world AI initiatives at major Canadian banks, such as RBC’s NOMI, TD’s AI Prism, BMO’s Lumi, which have introduced similar personalized insights, automated decisioning, and open banking capabilities.
2. Key Regulations and Institutional Risk Appetite
Northern Crown Bank operates under one of the most rigorous regulatory environments in Canada. As a Schedule I bank, it is subject to overlapping requirements from multiple authorities.
- OSFI (Office of Superintendent of Financial Institutions) – Primary prudential regulator, particularly Guideline B-13 (Technology and Cyber Risk Management) and expectations around operational resilience.
- PIPEDA and Provincial Privacy Laws – Strict rules on consent, safeguarding personal information, breach notification, and accountability.
- FCAC (Financial Consumer Agency of Canada) – Consumer protection and fair treatment obligations.
- FINTRAC – Anti-money laundering and terrorist financing controls.
- Emerging AI & Digital Regulation – Increasing expectations around model risk management, automated decision-making, and responsible AI use.
Risk Appetite
Northern Crown Bank maintains a low risk appetite for compliance, privacy, and operational risk that could impact customer trust or regulatory standing. It accepts moderate innovation risk in pursuit of competitive digital offerings (such as AI-powered personalization), provided that robust controls, clear governance, and ongoing monitoring are in place. Privacy is viewed not just as a compliance obligation, but as a core component of customer trust and the bank’s social license to operate.
In this function, the GRC must balance aggressive business objectives with rigorous regulatory and privacy expectations – requiring frequent judgment calls in ambiguous situations.
3. Use Cases and Materiality
Before assessing residual risk, the platform’s actual decisions need to be ranked. Not every AI feature creates the same harm if it fails.
| Use Case | What The Platform Does | Decision Type | Impact If It Goes Wrong | Rollout Posture |
|---|---|---|---|---|
| Personalized spending recommendations | Suggests budgets and next actions from transaction patterns | Advisory (not a binding yes/no) | Misleading advice, unfair product steering, privacy complaints | Can go live earlier with logging, consent, and quality monitoring |
| Automated credit decisioning | Limit increases or small-business approvals | Binding / high-consequence | Unfair lending, FCAC action, explainability failures | Shadow mode or limited low-amount / low risk cohort first; human review required |
| Real-time fraud detection | Flags suspicious transactions | Mixed (can block or only alerts) | False declines or missed fraud | Phased thresholds; manual fallback for uncertain cases |
| Open banking integration | Shares customer authorized data with third-party apps | Enabling / data sharing | Vendor breach, excess sharing, weak consent | Not an AI model by itself; treat as third party and API risk |
This ranking drives impact and how strong the controls are. It does not by itself set likelihood. Likelihood comes from how the platform is built and what the workshops showed (for example, product pressure for full profiling).
- Credit and fraud get the strongest model-risk, fairness, and human-review controls, because a wrong outcome can pose or refuse credit, or block a payment.
- Recommendations still need fairness, consent, and quality monitoring, but they are not the same decision class as credit. A customer can ignore the advice, so the impact is lower even if the offer is a poor fit.
- Open banking is assessed mainly as third-party, privacy, and API risk. It is not an AI credit model.
Impact in the register follows this table. Likelihood is scored separately.
For shadow mode, banks use two common patterns. Isolated shadow copies traffic into a second decision service that cannot write to core banking.
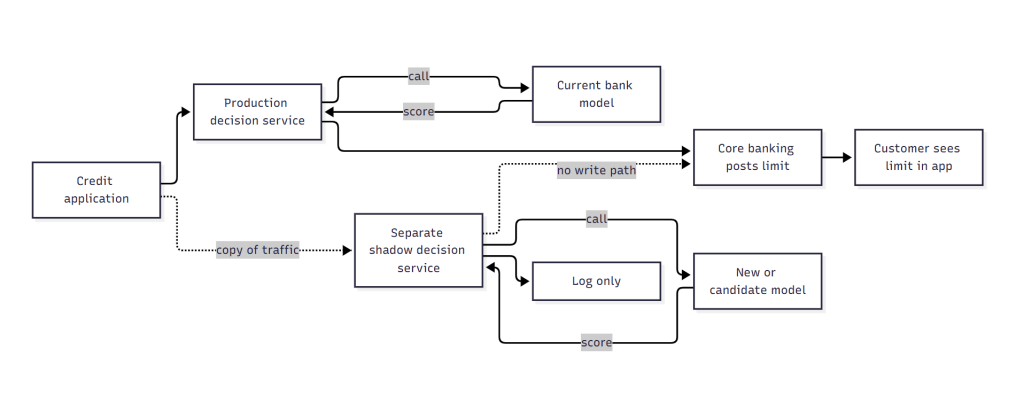
Same-engine shadow uses the live decision service and turns posting off after the model returns a score. Isolated is cleaner and more expensive. Same-engine is more common when the bank will not run two stacks.
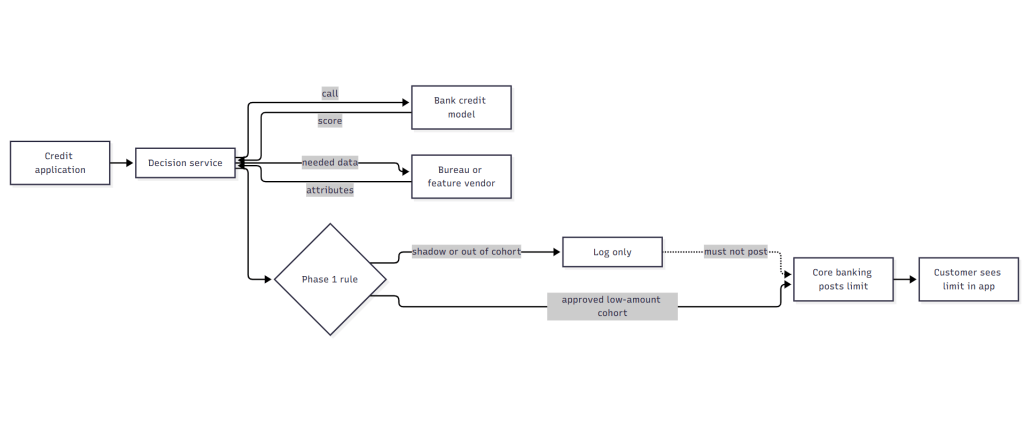
This case study uses same-engine shadow: the bank credit model may score a live application; the decision service must not post a limit unless the application is in the approved Phase 1 cohort. Testing and monitoring look for posts that skip that rule.
4. Risk Assessment for New AI-Powered Digital Banking Platform
This platform uses a hybrid model development approach. Core credit decisions and fraud detection models are developed primarily internally, while personalization capabilities leverage customized third-party and foundation models. This create both AI-specific risks and traditional third-party risks, which are assessed in the following sections.
Step 4.1: Review of Existing Enterprise Risk Register and Controls Baseline
In a large Canadian Schedule I bank like Northern Crown Bank, the enterprise risk register typically covers the following categories relevant to digital initiatives.
Typical Risks & Common Controls (by Category)
- Technology and Cyber Risk
Typical Risks: Ransomware attacks, phishing, cloud misconfigurations, insider threats.
Common Controls: multi-factor authentication, endpoint detection & response (EDR), regular penetration testing, network segmentation.
- Model Risk
Typical Risks: bias in AI models, lack of explainability, model drift, inaccurate prediction.
Common Controls: model validation frameworks, bias testing procedures, human oversight requirements, ongoing performance monitoring
- Third-Party Risk
Typical Risks: vendor data breach, weak contractual safeguards, concentration risk with key AI/cloud providers .
Common Controls: vendor due diligence questionnaires, contractual privacy clauses, ongoing vendor monitoring, right-to-audit clauses.
- Data Privacy Risk
Typical Risks: insufficient consent for profiling, unauthorized secondary use of data, cross-border transfer issue.
Common Controls: consent management platforms, data minimization techniques, privacy impact assessments (PIAs), data subject right processes.
- Consumer Compliance Risk
Typical Risks: unfair automated decisions, inadequate disclosure about AI use.
Common Controls: fairness testing, customer disclosure templates, complaint handling procedures.
For this assessment, I focus on portions of register most relevant to the new AI-powered digital banking platform. Specifically, I look for:
- Existing entries related to automated decision-making, AI/ML models, open banking APIs, and third-party AI services.
- Previous Privacy Impact Assessments for similar digital initiatives.
- Open Internal Audit or OSFI findings for similar digital initiatives.
- Current state of controls around data classification, consent management, model governance, and vendor oversight.
My Reasoning at This Step :
While the bank has strong foundational controls for traditional banking operations, these controls were primarily designed for static data processing. For the new AI platform involving real-time behavioral profiling and automated decisions, several gaps would likely exist – particularly in bias testing, explainability, and enhanced contractual requirements with third-party AI vendors. Additionally, the new platform is likely to reveal interconnected risks in legacy core banking systems that were not originally designed for high-volume, real-time AI data feeds.
Step 4.2: Conduct Targeted Stakeholder Workshops
To build a clear understanding of the new AI-powered digital banking platform, I would facilitate five targeted workshops with key stakeholders. Before each session, I prepare a focused agenda and specific questions based on known risks in AI banking initiatives. The goal is to translate business objectives into concrete data flows, technical dependencies, and risk scenarios.
In line with Three Lines of Defense model used in large Canadian banks, these workshops engage
- first Line (Business/Product teams) – who own day-today operations and initial risk identification;
- second line (Compliance, Privacy, Model Risk, etc,.) – who provide independent oversight and challenge.
This structured engagement helps me gather perspectives from both executing the work and those responsible for oversight.
Workshop Participants and Key Questions
Workshop 1: Product & Marketing Team
Sample Questions
- What specific personalized spending recommendations will AI provide?
- What behavior data (transaction history, spending categories, location patterns, etc.) will be used?
- How will customer interact with or opt out of these recommendations?
- What are the success metrics for the AI features (e.g. engagement rate, revenue impact, customer satisfaction)?
How Different Answers Reveal Different Risks
| Question | Possible Answer Range | Revealed Risks & Trade-offs |
|---|---|---|
| What specific personalized spending recommendations will the AI provide? | Conservative (“basic tips only”) vs Aggressive (“highly personalized using all historical + behavioral data”) | Aggressive approach → High privacy risk (extensive profiling), needs strong consent & transparency. Conservative → Lower privacy risk but may miss revenue targets. |
| What behavioral data (transaction history, spending categories, location patterns, etc.) will be used? | Limited (recent transactions only) vs Full history + location + spending patterns | Full history → Significant data minimization & consent challenges. Creates trade-off between personalization value and privacy compliance cost. |
| How will customers interact with or opt out of these recommendations? | Easy opt-out with clear explanation vs Buried settings | Poor opt-out → Higher FCAC complaint risk and reputational damage. Trade-off between user experience friction and regulatory safety. |
| What are the success metrics for the AI features (e.g., engagement rate, revenue impact, customer satisfaction)? | Purely revenue/engagement driven vs Balanced (trust + revenue) | Revenue-only focus → Strong pressure to over-collect data. Balanced metrics → Easier to justify privacy controls to business stakeholders. |
How I Use the Answers
The table above helps me quickly map business intent to privacy and compliance risks. For example, if Product pushes for aggressive personalization using full behavior data while setting revenues as the top success metric, I highlight the clear trade-off between short-term engagement and long-term regulatory and trust risks.
I would then recommend specific controls to leadership:
- Granular consent: Instead of one broad “accept all” checkbox, we ask separate permissions such as “Allow us to use your full transaction history for personalized spending recommendations?” and “Allow location data for better fraud detection?”
- Data minimization options: Offer customer a “basic mode” that uses only the last 3 months of spending categories instead of a full 2-year history + location data.
- Transparency features: Show clear in-app explanations before enabling the feature (e.g., “We analyze your spending to suggest ways to save money. You can turn this off anytime in Settings.” and provide easy opt-out paths.
I would recommend these trade-offs and residual risks (e.g., medium instead of High) directly in the risk register for leadership review.
Example Leadership Discussion
Me:” The aggressive personalization approach could deliver strong revenue uplift, but it carries material privacy risk under PIPEDA due to extensive behavioral profiling. My recommendation is to set Basic Mode as default, with clear and easy opt-in for personalization.”
Business Lead: “But if we make Full Mode opt-in, won’t most users just stick with Basic and feature becomes less valuable?”
Me:” That’s a fair concern. If Basic Mode feels too limited, adoption will suffer. My suggestion is to make the basic mode genuinely useful while making the upgrade to Full Mode simple and clearly beneficial. We can A/B test both models after launch and monitor engagement metrics. The keeps regulatory risks at Medium while still giving us a path to high engagement.”
Workshop 2: IT/Development & Data Science Team
Sample Questions
- Which legacy core banking systems will feed data into the AI models and what are their current logging and audit capabilities?
- What third-party AI models or cloud services will we use?
- How will real-time transaction data be ingested and processed?
- What are the main integration points with open banking APIs?
- How will model outputs be monitored for drift and performance issues after launch?
Context Regarding Legacy Systems (for Question 1)
Most large Canadian banks still run core banking transactions on legacy mainframes (often COBOL-based) while using modern cloud systems for customer-facing and AI layers. When connecting the two, banks face real challenges.
| Aspect | Legacy Mainframe | Modern AI Layer | Resulting Trade-off |
|---|---|---|---|
| Data Flow | Batch processing (daily/hourly) | Real-time streaming | Need middleware or complex integration → higher complexity and potential points of failure |
| Logging & Audit | Limited real-time logging | Requires detailed, real-time audit trails | Extra work to add logging or workarounds → increased cost and technical debt |
| Performance | Not designed for high-speed AI queries | Needs fast access | Performance bottlenecks or latency issues |
| Security & Compliance | Older security standards | Modern security expectations | Additional controls needed to bridge the gap → higher cost and risk during transition |
The real world reality becomes trade-offs in how the banks connect the legacy and the modern.
Cheaper/Faster option: Quick-and-dirty integration. The team takes shortcuts to make it work faster/cheaper in the short term:
- Using temporary scripts, direct database connections, or batch file transfers instead of proper real-time APIs.
- Skipping comprehensive security reviews, detailed logging, or proper error handling.
- Hard-coding some connections or using quick middleware without full testing.
- Accepting higher operational risk (e.g. occasional downtime, manual workarounds, weaker audit trails)
Results: It works great for the launch, but it creates technical debt, higher long-term maintenance costs, security vulnerabilities, and compliance risks.
Safer/Slower option: Invest in modernization, better middleware, API layers, or gradual migration (higher upfront cost, slower launch, but lower long term risks).
How Different Answers Reveal Different Risks
| Question | Possible Answer Range | Revealed Risks & Trade-offs |
|---|---|---|
| Which legacy core banking systems will feed data into the AI models, and what are their current logging and audit capabilities? | Mix of old mainframe (core transactions) and modern systems (digital channels) | Hybrid setup → High interconnected risks (data synchronization issues, inconsistent logging/audit trails, performance bottlenecks). Trade-off between leveraging reliable existing core systems (lower replacement cost) and the investment required for robust middleware, modernization, or workarounds (higher upfront cost but lower long-term risk). |
| What third-party AI models or cloud services will we use? | In-house models vs Heavy reliance on external vendors | Heavy reliance → High third-party risk (data breaches, vendor lock-in, limited visibility). Trade-off between faster development and control over data/privacy. |
| How will real-time transaction data be ingested and processed? | Batch processing vs True real-time streaming | Real-time → Expanded attack surface and higher breach risk. Trade-off between feature responsiveness and security/compliance complexity. |
| What are the main integration points with open banking APIs? | Minimal exposure vs Deep integration (AIS – Account Information Services, PIS – Payment Initiation Services, real-time bidirectional) | Deep integration → Increased data sharing risk and compliance burden. Trade-off between ecosystem value and privacy exposure. |
| How will model outputs be monitored for drift and performance issues after launch? | Basic periodic checks vs Real-time drift & performance monitoring | Weak monitoring → Higher model risk (inaccurate decisions over time). Trade-off between operational cost and regulatory safety. |
How I Use the Answers
The answers help me identify both direct technical risks and interconnected dependencies with legacy systems. For example, if the team says they plan to rely heavily on an external AI vendor while legacy mainframe systems have limited logging capabilities, I flag high third-party risk and auditability gaps. I would then recommend specific controls to leadership:
- Enhanced vendor contractual clauses (where negotiable):
- Right-to-audit clauses (limited to security and privacy aspects)
- Specific data residency and deletion requirements (e.g., data must stay in Canada or be deleted within 30 days of contract end)
- Stricter breach notification timelines (within 24 hours)
- AI-specific addendums (bias testing reports, training data transparency, sub-processor approval rights).
- Real-time monitoring dashboards. This means building or using dashboards (in ServiceNow, Splunk, Datadog, or the bank’s SIEM) that show:
- Model performance and drift metrics
- Data quality score
- API call volumes and error rates
- Vendor service health
- Privacy-related alerts (e.g., unusual data access patterns)
We will also initiate a phased integration plan as a third control, since large banks cannot usually flip a switch to full real-time integration between old mainframes and new AI layers. The legacy systems were built for batch processing (daily runs), not real-time streaming. Going full real-time from day 1 is often too risky or technically difficult.
Breakdown of the Phased Plan
Phase 1: Basic integration with Monitoring and Manual Fallbacks
- Use batch processing or scheduled file transfers (for example every 15-60 minutes) instead of true real-time feeds.
- Add basic monitoring (dashboards showing data flow success rates, errors, and delays).
- Keep new middleware light – existing ETL tools or simple jobs.
- Goal: Stand up a controlled path from legacy systems to the AI layer so the bank can observe data quality and model behavior before expanding exposure.
- What goes live in Phase 1: advisory features and fraud flags can run with monitoring; automated credit stays in shadow mode or is limited to low-amount / low-risk profiles with human review and a kill switch. Shadow output are written to the decision log, not connected to core posting. They must not post a limit unless the application is in the approved cohort and the decision service posts it.
- What Phase 1 is not: a public beta of full automated credit.
- Trade-off: Features are slower and less real-time; more manual review. Third-party and auditability risk stay bounded.
This phase still creates some technical debt (temporary solutions), but it’s manageable and common.
Phase 2: Add Real Time Data Feeds (Stabilization)
- Implement proper real-time feeds (e.g., using Kafka, API gateways, or message queues) and middleware layers.
- Significantly Improve logging and audit trails on the legacy side (or add middleware that captures logs)
- Strengthen monitoring and alerting.
- Goal: Make the system more observable. The monitoring tools built here become the foundation for handling higher volumes and more complex AI transactions
- Scope Note: Real-time feeds does not automatically mean full automated credit. Credit stays limited until Model Risk signs off on live fairness and drift results.
- Why not do this from the beginning? Because it requires more time, testing, and changes to the legacy systems. Doing it in Phase 1 would likely delay the entire project significantly.
Phase 3: Gradual Modernization and a Durable Integration Layer
- Long-term: put stable APIs in front of legacy functions the AI platform must call (wrap), then replace the highest-friction functions behind those APIs when the bank can do it without disrupting core banking.
- Build a dedicated integration layer so the AI platform talks to one contract, not raw mainframe jobs.
- Improve near-real-time paths where the business case is strong (fraud signals, limit checks). Do not assume every core posting flow becomes streaming.
- Why later? Replacement is expensive and operationally risky. Wrapping first lets the bank modernize in slices.
- Limit: Wrapping doesn’t remove mainframe constraints. If the system of record is still batch, some AI features will stay near-real-time, not instant.
- Scope note: This is an infrastructure goal. High-impact credit decisions still follow the use-case rollout posture.
Example Leadership Discussion
Me: “Using external AI components against mainframes with weak real-time logging leaves high third-party and auditability risk. We should strengthen vendor clauses, stand up monitoring, and use a phased integration plan.”
IT/Technical Lead: “That will delay the launch. Can’t we accept some of that risks to move faster?”
Me: “We can meet a launch date, but phase 1 is a limited, reversible rollout – not full automated credit for every customer. We start with batch feeds, basic monitoring, and manual fallbacks. Advisory features and fraud flags can run with monitoring. Automated credit stays in shadow mode or small low-amount cohort with human review and a kill switch.
Phase 1 does not make the vendor safer. Stronger contracts, least-privilege access, and audit rights reduce the vendor risk itself. The phased rollout limits how much data and how many decisions sit on the new path while logging is still weak. Dashboards and a kill switch help us detect and contain a failure faster. That lowers auditability risk and the impact of a third-party incident. Together, residual auditability risk and third-party impact can sit at Medium instead of High. Inherent vendor risks stay High until the contract and oversight catch up. I have documented the trade-off in the risk register. “
Workshop 3: Legal & Privacy Team
Sample Questions
- What consent model will we use for behavior profiling in the AI personalization engine?
- How will we handle cross-border data transfers for U.S. operations?
- What privacy-by-design requirements should be built into the AI decision engine?
- How will we handle data subject rights (access, deletion, portability) for AI-generated profiles?
- What are the key privacy risks should we prioritize for this platform?
How Different Answers Reveal Different Risks
| Question | Possible Answer Range | Revealed Risks & Trade-offs |
|---|---|---|
| What consent model will we use for behavioral profiling in the AI personalization engine? | Broad “accept all” consent vs Granular / purpose-specific consent | Broad consent → High PIPEDA compliance risk and potential regulatory fines. Granular consent → Lower risk but higher implementation cost and possible lower user adoption. |
| How will we handle cross-border data transfers for U.S. operations? | Standard transfers vs Transfers with strong safeguards (e.g., SCCs – Standard Contractual Clauses or data localization) | Inadequate safeguards → High risk of PIPEDA violations and regulatory action. Strong safeguards → Lower risk but higher operational complexity and cost. |
| What privacy-by-design requirements should be built into the AI decision engine? | Minimal (add privacy later) vs Strong (built from the beginning) | Minimal → High risk of rework and regulatory findings. Strong privacy-by-design → Lower long-term risk but slower development timeline. |
| How will we handle data subject rights (access, deletion, portability) for AI-generated profiles? | Manual processes vs Automated / scalable processes | Manual → High operational risk and scalability issues. Automated → Lower risk but requires significant investment in systems. |
| What are the key privacy risks we should prioritize for this platform? | Focus only on consent vs Comprehensive view (consent + bias + third-party + cross-border) | Narrow focus → Higher chance of missing material risks. Comprehensive view → Better risk coverage but requires more time and resources. |
How I Use the Answers
The answers help me evaluate compliance gaps and recommend balanced controls. For example, if the team says they prefer broad consent for simplicity, I highlight the elevated PIPEDA risk and recommend moving to granular consent with clear opt-in mechanisms. I would then propose specific mitigations such as enhanced transparency notices, easy opt-out paths, and stronger contractual requirements for cross boarder transfers. This allows me to provide leadership with practical trade-off options between speed of launch and regulatory safety.
Example Leadership Discussion
Me:” Using board consent for the AI personalization engine would simplify the user experience, but it carries material PIPEDA compliance risk due to extensive behavioral profiling. My recommendation is to implement granular consent, stronger privacy-by-design features, and clear transparency notices.”
Privacy Lead: “Granular consent will add operational complexity and might slow down the launch. We also need to ensure we can handle data subject rights requests at scale for AI-generated profiles.”
Me: “I agree on the complexity concern. We can set Basic mode as the default (still useful) and make Full Personalization an easy opt-in. For data subject rights, I recommend moving from manual processes to automated ones using dedicated APIs. This reduces long-term operational burden while staying compliant. Overall, this keeps residual privacy risk at Medium instead of High. I’ve documented the trade-offs in the risk register – we can review it together with Product team next week.”
Workshop 4: Model Risk Team
Sample Questions
- How do we test and document bias in AI credit scoring and fraud detection models before launch?
- What fairness testing will continue after the models are live, and on which population?
- What explainability is required for automated decisions to meet OSFI E-23 and FCAC expectations?
- How will model drift be detected and addressed after go-live?
- Which decisions stay in shadow mode or require human review in Phase 1?
How Different Answers Reveal Different Risks
| Question | Possible Answer Range | Revealed Risks & Trade-offs |
|---|---|---|
| How do we test and document bias in AI credit scoring and fraud detection models before launch? | Basic statistical checks vs testing across relevant groups and decision outcomes | Basic checks → higher risk of unfair credit outcomes and regulatory challenge. Stronger testing → lower risk, more time and cost. |
| What fairness testing will continue after the models are live, and on which populations? | One pre-launch test vs repeat testing on the live population as exposure grows | A launch-only test can miss bias that appears only in production. Ongoing testing on the actual cohort costs more, but it is what “phased fairness testing” means. |
| What explainability is required for automated credit decisions to meet OSFI E-23 and FCAC expectations? | Generic model notes vs applicant-level reasons that a reviewer can check | Weak explainability → customers and reviewers cannot challenge a decision. Stronger explainability → more engineering work. |
| How will model drift be detected and addressed after go-live? | No production monitoring vs defined metrics, thresholds, and owners | No monitoring → a model that was acceptable at launch can become unfair later. Active monitoring → needs tools and a response process. |
| Which decisions stay in shadow mode or require human review in Phase 1? | Full automated credit on day one vs limited cohort / low-amount / human review | Full automation too early → residual risk stays High. Bounded rollout → residual risk can be Medium if monitoring and a kill switch exist. |
How I Use the Answers
These answers tell me whether model validation is strong enough for a binding credit decision. If the plan is only basic bias checks and no production drift monitoring, I treat model risk as High. I then recommend independent validation, documented fairness tests, applicant-level explanations for credit, and a limited Phase 1 population. Chain-of-thought or prompt logs are not treated as sufficient explainability for automated credit.
Example Leadership Discussion
Me: “Basic bias testing and no live drift monitoring leaves automated credit at High model risk. OSFI E-23 expects validation through the model lifecycle, not only at launch.”
Model Risk Lead: “We can require independent validation and production monitoring, but that affects the timeline”
Business Lead: “Can we still launch something?”
Me: “Yes. Keep full automated credit in shadow mode or limit it to low-amount decisions with human review. Expand only after the first fairness and drift results are acceptable. This is what ‘phased fairness testing’ means: test the actual live population as exposure grows, not a weaker version of fairness. Residual risk can sit at Medium for Phase 1 if the population is bounded and we have a kill switch.”
Workshop 5: Compliance / Consumer Protection Team
Sample Questions
- How will we stay compliant with consumer-protection rules for AI-driven after launch?
- What process will handle customer complaints about automated recommendations or credit outcomes?
- What disclosures do customers see when AI is used in a decision that affects them?
- How will we incorporate new FCAC guidance or other rule changes?
- If recommendations or product offers vary by region or customer segment, how do we stop unfair steering?
How Different Answers Reveal Different Risks
| Question | Possible Answer Range | Revealed Risks & Trade-offs |
|---|---|---|
| How will we stay compliant with consumer-protection rules for AI-driven after launch? | Occasional reviews vs an owner, testing calendar, and evidence trail | Occasional reviews miss rule changes. A simple owned process is enough; it does not need heavy new framework |
| What process will handle customer complaints about automated recommendations or credit outcomes? | Ad hoc emails vs logged complaints, timelines, and a path to human review | Weak complaint handling is a consumer-protection failure, especially for automated credit |
| What disclosures do customers see when an AI is used in a decision that affects them? | Generic website text vs clear notice at the decision point | Weak disclosure makes decisions harder to challenge and easier to criticize |
| How will we incorporate new FCAC guidance or other rule changes? | Wait for a finding vs a named owner who tracks FCAC/OSFI updates | Reactive updates create gaps between rule changes and model/guardrail updates |
| If recommendations or product vary by region or customer segment, how do we stop unfair steering? | No segment analysis vs periodic review of who is offered which products | Advisory features can still create fairness and conduct risk even when they are not yes/no credit decisions |
How I Use the Answers
Compliance is about conduct after the model is in market: disclosures, complaints, and rule changes. I do not treat this as a second model-validation workshop. If complaint handling and disclosures are weak, I raise consumer-protection risk even when Model Risk is comfortable with the statistics.
Example Leadership Discussion
Me: “Model validation can be acceptable and we can still fail consumer protection if customers cannot complain about an automated decision or cannot tell what AI was used.”
Compliance Lead: “We need a logged complaint path and a human review route for credit outcomes.”
Business Lead: “Will that slow the launch?”
Me: “Not if we reuse existing complaint processes and add an AI-decision flag. The control is ownership and evidence, not a new department.”
Step 4.3: Map Data Flows, Systems, People, and Third-Party Dependencies
Workshops and mapping check each other. Workshops capture what teams think happens and which trade-offs they will accept. Mapping follows the actual path. Either can reveal more than the other.
Key Analysis Area and Sample Questions + What I Look For
Data In and Data Movement
Sample Questions:
- What personal, credit, and behavioral data actually enter each AI feature?
- After that data leaves the mainframe or source system, which systems does it hop through before a decision is shown to a customer or an officer?
- Are there manual steps or temporary files on that path (Excel fixes, SFTP drops, shared folders, emailed extracts)?
- If a customer complains about one decision, can we pull a decision ID, model version, inputs used, output, and any human change?
What “Data Path” And “Trace a Complaint” Mean Here
A hop is one handoff between systems or to a person. For this platform a typical credit path is: mainframe extract -> batch file -> feature store -> model (internal and/or vendor) -> decision service -> channel or official queue – audit log.
Manual hops are part of that path: Excel fixes, SFTP drops, emailed extracts. They often have no decision ID.
To answer one complaint, we need a decision record, not a chain-of-thought story: Decision ID, time, model version, input used, output/reason codes, any human override, and a vendor call ID if a third party scored it. Pipeline lineage tools show how feeds actually move. They do not replace that per-decision log.
Phase 1 will not eliminate mainframe logging gaps. This step marks which hops are unlogged so monitoring and manual fallback attach there, and so “human in the loop” is a logged override, not an email.
What I look for / hidden issues: Unnamed hops, scratch files, and decision records that cannot be rebuilt. Legacy logging gaps are expected; the point is to mark where they sit so Phase 1 monitoring and fallback attach to those hops.
Systems and People
Sample Questions:
- Which systems are system-of-record, feature store, model runtime, channel, and logging?
- What can change a model input, a threshold, or an automated credit outcome?
- If a human is in the loop, is that override logged?
What I look for / hidden issues: privileged users with no audit trail, and phase 1 “manual fallback” that is actually an unlogged Excel process.
Third-Party Dependencies
Sample Questions:
- Which third-party services have access to customer data, and what is the exact scope?
- Do we have visibility into their sub-processors?
- What happens if one vendor has an outage or breach – what is our fallback?
What I look for / hidden issues: over-reliance on a single vendor, weak contractual safeguards, no right-to-audit, limited visibility into sub-processors, and no fallback if that vendor has an outage or breach. I also check whether a vendor is already on a live path that Phase 1 said should stay limited (for example fully automated credit).
My Reasoning at this Step
By reviewing the actual hops – systems, people, files, and vendors – I can line up business intent with how the platform really runs. Workshops say what teams think happens and which trade-offs they will accept. Mapping shows the path those decisions travel. Either view can be richer then the other. The point of this step is to put both against the same credit, recommendation, fraud, and open-banking paths so unlogged handoffs, manual workarounds, and vendor dependencies are named before we score residual risk.
Step 4.4: PIA-style Assessment and Risk Scoring
After the data-flow and vendor mapping, I run a PIA-style assessment: purpose, data categories, flows, privacy risks, and residual ratings. That drives the risk register. A full signed PIA (Privacy Impact Assessment) would add lawful basis or equivalent consent analysis, retention, and a formal sign-off. Those are not published here as a standalone artifact.
Project Description & Scope
The AI platform includes personalized spending recommendations, automated credit decisioning, real-time fraud detection, and open banking API integrations. It processes large volume of personal financial and behavioral data across millions of customers.
Data Mapping & Inventory
I map the data lifecycle:
- Sources: Legacy code banking systems (transaction history, account balances), behavior signals (location, spending patterns).
- Processing: AI models for personalization and automated decisions.
- Sharing: Open banking APIs with third-party apps.
- Retention: AI-generated profiles stored for up to 24 months.
Privacy Risk Identification & Evaluation
| Privacy Risk | Description | Likelihood | Impact | Overall Rating | Key Concern | Register ID |
|---|---|---|---|---|---|---|
| Insufficient granular consent for behavioral profiling | Personalization uses full transaction and location data without separate opt-in. Product pressure for rich profiling makes this likely unless Basic Mode is default | High | High | Critical | PIPEDA consent and purpose limitation | RA-01 |
| Bias or lack of explainability in automated credit decisions | Credit models can produce unfair or unexplainable outcomes. Phase 1 limits live exposure. | Medium | High | High | FCAC fair treatment + OSFI E-23 model risk | RA-02 |
| Third-party AI vendor access and oversight | External AI providers may have broad data access and weak contractual or monitoring rights | High | High | Critical | OSFI B-13 third-party risk + PIPEDA accountability | RA-03 |
| Cross-border data transfers to U.S. operations | Customer data sent to U.S. operations without adequate contractual or localization safeguards. | Medium | Medium | Medium | PIPEDA international transfer rules | RA-07 |
Recommendations & Residual Risk
I recommend the following targeted mitigation:
- Insufficient granular consent: Implement granular consent mechanisms (separate opt-in for full behavioral profiling) and set Basic Mode as default.
- Bias or lack of explainability: Require regular bias testing, feature importance scores for automated decisions, and human oversight for high-impact decisions.
- Third-party AI vendor risks: Strengthen vendor contracts with right-to-audit clauses, specific data residency and deletion requirements, stricter breach notification timeline (within 24 hours), sub-processor approval rights, and AI specific addendums for bias testing and training data transparency.
- Cross-border data transfers: Use Standard Contractual Clauses (SCCs) or data localization where feasible.
After implementing these controls, I reassess the risks and reduce most of them to Medium residual risk (the risk that remains after applying controls). For example, the third-party AI vendor risk drops from Critical to Medium with stronger contracts and monitoring in place.
Step 4.5: Overall Risk Register Summary
After completing the baseline review, stakeholder workshops, data flow analysis, and Privacy Impact Assessment, I update the relevant portions of the enterprise risk register for the new AI-powered digital banking platform.
Summary of Key Risks
| Risk ID | Risk Statement | Likelihood | Impact | Overall Rating | Recommended Controls | Residual Risk | Origin |
|---|---|---|---|---|---|---|---|
| RA-01 | There is a risk that the personalization design could use full transaction and location data without granular opt-in, leading to processing beyond a PIPEDA-compliant purpose and to regulatory or complaint exposure. | High | High | Critical | Granular consent opt-in for full profiling; Basic Mode default; transparency notices; quality monitoring for advice and unfair steering | Medium | Product workshop + PIA |
| RA-02 | There is a risk that biased training data or weak explainability in credit models could produce unfair automated decisions, leading to customer harm and FCAC / OSFI E-23 action. | Medium | High | High | Bias testing before launch and on the live cohort; applicant-level reasons; human review for high-impact decisions; Phase 1 shadow mode or low-amount cohort with a kill switch; logged complaint path and disclosure at the decision point. | Medium | Model Risk + Compliance workshops |
| RA-03 | There is a risk that an AI vendor could use weak contracts and limited oversight, leading to breach, misuse, or loss of control over customer data. | High | High | Critical | Stronger AI vendor clauses (audit rights when negotiable, residency/deletion, 24-hour notice, sub-processor approval); where audit rights or log export cannot be negotiated, document the gap and apply compensating controls (segmented access, less data in Phase 1, more frequent reviews, insurance / termination rights); vendor monitoring; Phase 1 limits how much live credit data the vendor sees; if the model or vendor is unavailable, credit refers or declines – it does not fail open | Medium | IT workshop + vendor mapping |
| RA-04 | There is a risk that attackers or a partner could exploit open-banking APIs and excess scope, leading to unauthorized access, delayed detection, or sharing beyond customer authorization. | Medium | High | High | API security and monitoring; share only authorized scopes; partner/vendor controls from RA-03 | Medium | Use cases + mapping |
| RA-05 | There is a risk that unlogged legacy hops or manual workarounds could prevent reconstruction of an AI decision, leading to investigation and complaint-handling failure. | High | Medium | High | Phased integration; log the named hops; decision record required; Phase 1 manual fallback must be a logged override, not an email; if the model or vendor is unavailable, credit refers or declines – it does not fail open | Medium | Data-flow / systems-and-people mapping |
| RA-06 | There is a risk that AI profiling could retain more behavioral data or keep it longer than needed, leading to PIPEDA minimization failure. | Medium | High | High | Data minimization options; timed deletion of behavioral profiles | Low-Medium | PIA minimization |
| RA-08 | There is a risk that model drift after go-live could degrade automated outputs, leading to inaccurate credit or fraud decisions (higher harm than weak recommendations). | Medium | High | High | Automated drift detection and regular model retraining processes; credit and fraud alerts get a faster review when drift is flagged than recommendation quality issues; quality monitoring for recommendations | Medium | Model Risk workshop |
| RA-07 | There is a risk that transfer to U.S. operations could proceed without adequate contractual or localization safeguards, leading to a PIPEDA transfer failure. | Medium | Medium | Medium | Standard Contractual Clauses(SCCs) and/or data localization where feasible | Low | Legal/Privacy workshop |
| RA-09 | There is a risk that recommendation models could steer customers toward the bank’s or a partner’s products that are a poor fit, or treat similar customers differently, leading to complaints and conduct findings even when consent was collected. | Medium | Medium | Medium | Log the offer; allow opt-out; sample who sees which product; tie “wrong products” complaints to recommendation ID | Low-Medium | Product workshop + Use Cases |
Key Takeaways
- The new AI platform introduces several Critical and High risks, particularly in privacy, third-party oversight, model governance, and legacy system integration.
- While the bank has strong foundational controls for traditional banking, significant gaps exist in AI-specific areas.
- With the recommended controls, most risks can be reduced to Medium residual risk.
- These findings will drive targeted policy updates, control enhancements, and ongoing monitoring in the following sections.
5. Governance & Policy Development
After completing the risk assessment and PIA, I reviewed the bank’s existing governance documents to determine necessary updates for the new AI-powered digital banking platform.
My Review Process
I followed a structured approach: mapping PIA-identified risks to existing policy language, evaluating specificity and enforceability, and focusing on practical improvements that bridge identified gaps.
Existing Responsible AI Policy (for reference)
[Link] Imperfect Responsible AI Policy for Northern Crown Bank
Key Gaps Identified and Updates Executed
In total, I identified nine gaps in the existing Responsible AI Policy. Below are four of the most significant ones, along with the targeted updates I executed. The full updated policy is available in the Resources section.
Gap 1: Transparency & Explainability
The existing policy mentioned transparency as a principle but provided no concrete requirements for customer-facing decisions.
Update Executed
“For all high-impact AI systems (including automated credit decisions and personalized recommendations), the Model Owner must ensure that the feature importance explanations or equivalent explainability methods are available. Customers will be provided with clear and accessible explanations upon request or as part of the decision process, to ensure transparency and address the risk of unfair or opaque automated decisions.”
Why this Update?
It directly addresses the High Risk of lack of explainability identified in PIA and makes the principle actionable.
Gap 2: Behavioral Profiling & Granular Consent
The policy had only a general statement about complying with privacy laws, with no specific guidance on behavioral profiling.
Update Executed
“For any behavioral profiling or use of non-essential customer data in AI models, the Business Unit Owner must ensure that granular consent is obtained. A “Basic Mode” using only minimal necessary data must be offered as the default option, with clear customer-facing explanations, to comply with PIPEDA consent principles and reduce privacy risk.”
Gap 3: Model Drift Monitoring
The existing policy stated that AI systems “should be monitored” but gave no frequency or escalation process.
Update Executed
“For all production AI models, the Model Owner must implement automated drift detection mechanisms and monitor model performance at least quarterly. Results must be documented and escalated to Chief AI Officer if predefined thresholds are breached, to maintain accuracy and prevent degraded or biased decision-making. “
Why This Update?
It turns a vague statement into an enforceable control that addresses model risk.
Gap 4: Accountability & Roles
Only the Chief AI officer was mentioned, with no clarity on other teams.
Update Executed
Revise the Governance section to:
“The Chief AI Officer has overall accountability for Responsible AI program. Business Unit Leaders must ensure compliance with this policy within their areas and escalate material risks to the GRC team. Development and Data Science teams must implement required controls and report identified risks, to maintain clear ownership and effective risk management across the organization. “
Why This Update?
Clear accountability reduces confusion and supports effective execution across teams.
Summary of Changes
These updates transform high-level principles into more enforceable and risk based requirements. Key improvements include clearer accountability across business units and control functions, specific explainability requirements for high-impact AI systems, granular consent mechanisms for behavioral profiling, defined model drift monitoring and escalation processes, and stronger governance over third-party AI vendors. Detailed implementation procedures will be documented in supporting guidelines and standards.
Updated Responsible AI Policy (full version):
[Link] Updated Responsible AI Policy for Northern Crown Bank
Existing Third-Party Risk Management Policy (for Reference)
[Link] Imperfect Third-Party Management Policy for Northern Crown Bank
Key Gaps Identified and Updates Executed
In total, I identified 12 gaps in the existing Third-Party Risk Management Policy. Below are the five most significant ones, along with the targeted updates I executed. The full updated policy is in the Resources section.
Gap 1: Lack of Formal Risk Assessment and Classification Framework
The existing policy does not require a structured, risk based process to assess and classify third-party vendors according to their criticality, data sensitivity, or potential impact on the Bank.
Updated Executed
“The bank must establish and maintain a formal risk assessment and classification framework for all third-party vendors. Vendors must be assessed based on factors like data access, service criticality, and regulatory exposure, and classified into risk tiers (Critical, High, Medium, Low). Enhanced due diligence, contractual requirements, and monitoring must apply to higher-risk tiers.”
Why This Update?
It turns vague requirement into a clear, risk-based process aligned with OSFI B-10 expectations.
Gap 2: Unclear Accountability and Ownership
The policy does not clearly define roles and responsibilities using the three Lines of Defense model.
Update Executed
“Business Unit Leaders and senior managers (First Line) are accountable for the overall vendor relationship. This includes managing the commercial and operational aspects of the relationship (such as performance, service delivery, and day-to-day interactions) and ensuring that risks associated with the vendors are identified, assessed, and managed in accordance with the Bank’s risk management framework. The GRC team, Information Security, and Privacy (Second Line) provide independent risk assessment, oversight, and challenge. Internal Audit (Third Line) provides independent assurance.”
Why This Update?
Clear ownership and escalation paths improve accountability and execution.
Gap 3: Absence of Central Inventory/Register
The policy does not require the Bank to maintain an up-to-date inventory of third-party relationships, including AI vendors and their sub-processors.
Update Executed
“The GRC team must maintain a central, enterprise-wide register of all third-party vendor relationships. The register must include vendor details, services provided, data processed, risk classification, contract details, and sub-processor information. Business units must notify the GRC team of any new or changed relationships.”
Why This Update?
A central register provides visibility and supports effective risk oversight across the organization.
Gap 4: Missing Strategy and Contingency Planning
The policy contains no requirements for exit strategies, data return or deletion, or contingency planning in the even of vendor failure or contract termination.
Update Executed
“For Critical and High-risk vendors, exit and contingency plans must be developed during initial assessment and contract negotiation. These plans must address data return or secure deletion, knowledge transfer, and alternative arrangements. Plans for critical vendors must be tested periodically.”
Why This Update?
Exit planning reduces operational and data risk in the event of vendor disruption or termination.
Gap 5: Inadequate Ongoing Monitoring, Re-assessment, and Multi-Jurisdiction Risk Management
Ongoing monitoring is mentioned only at high level, with no defined re-assessment triggers or consideration or multi-jurisdictional risks.
Update Executed
“Vendors must be subject to ongoing monitoring with defined frequency and triggers for re-assessment (e.g., material incidents, changes in sub-processors, regulatory changes, or performance issues). Critical and High-risk vendors, particularly those involving cross-border data processing, must undergo enhanced monitoring. The bank must assess and mitigate multi-jurisdictional risks, including data transfer mechanisms and compliance with the strictest applicable standards (PIPEDA, GDPR, CCPA, etc,.). Clear incident notification timelines shall be defined in contracts.”
Why This Update?
It makes monitoring enforceable and addresses the real-world complexity or cross-border AI vendors.
Summary of Changes
These updates transform a high-level and vague policy into a practical, risk-based, and auditable framework. Key improvements include a formal risk assessment and classification process with clear risk tiers, clearer accountability using the Three Lines of Defense model, establishment of a central vendor register, exit strategy and contingency planning requirements, and specific consideration of multi-jurisdictional and cross-border risks. Detailed implementation procedures will be documented in supporting guidelines and standards.
Updated Third-Party Risk Management Policy (full version):
[Link] Updated Third-Party Risk Management Policy for Northern Crown Bank
6. Controls Design & Implementation
This section outlines the key controls designed to mitigate the risks identified in the risk assessment. The controls are developed with reference to the NIST AI RMF 1.0, the German Kriterienkatalog for the integration of external generative AI models, OSFI B-10 (Third-Party Risk Management Guideline), PIPEDA, and NIST SP 800-53. Each control includes the responsible owner and a high-level implementation approach.
Key Controls for RA-01: Insufficient Granular Consent in AI Personalization Engine
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-01-C01 | Implement granular consent mechanisms with clear options for data use in AI personalization. | Privacy / GRC | Update consent management system with “Basic Mode” default and clear explanations. | PIPEDA Principle 3 (Consent) |
| RA-01-C02 | Conduct regular privacy impact assessments for AI personalization features. | Privacy + Model Risk | Perform PIA before new features and at least annually. | PIPEDA Principle 4 & 5 + German Kriterienkatalog Section 2.2 |
Key Controls for RA-02: Bias in AI Credit Decisioning Models
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-02-C01 | Require third-party components in credit models to undergo independent bias/fairness audits with remediation commitments. | Model Risk + Procurement | Include specific clauses in vendor contracts and due diligence checklists. | GOVERN 6.1 & 6.2 + MANAGE 3.1 & 3.2 |
| RA-02-C02 | Perform regular internal bias and fairness testing on credit decisioning models. | Model Risk Management | Run tests before deployment and quarterly in production; document results. | MEASURE 2.11 |
| RA-02-C03 | Implement human-in-the-loop review for high-risk or borderline credit decisions. | Credit Operations | Define thresholds and automate routing to human reviewers. | MANAGE 1.2 & 2.1 |
| RA-02-C04 | Maintain a documented Bias Incident Response Playbook. | GRC + Model Risk Management | Create playbook and test it at least annually. | MANAGE 4.1 |
| RA-02-C05 | Monitor credit models for data drift and fairness metric changes with automated alerts. | Model Risk + InfoSec | Set up monitoring dashboard with defined thresholds. | MANAGE 3.2 + supporting MEASURE activities |
| RA-02-C06 | Phase 1 automated credit shall run in shadow mode or only for a low-amount/low risk cohort, with human review and a kill switch. Expansion into broader automated credit requires documented live fairness and drift results. | Model Risk + Credit Operations | Encode cohort limits and the kill switch in the decision service. Keep a human queue for in-scope applications. Model Risk records the evidence pack before the cohort is widened. | OSFI E-23 (lifecycle validation); MANAGE 1.2 / 2.1 |
| RA-02-C07 | Customers shall have a logged complaint path and a clear notice when AI is used in credit decisions, including a route to human review. | Compliance + Credit Operations | Reuse the existing complaint system with an AI-decision flag, Decision ID, and route the case to human review within the bank’s complaint-handling timeline. Show a short notice at the decision point, not only in a website footer. | FCAC fair treatment; PIPEDA Principle 8 (openness) |
Key Controls for RA-03: Weak Contractual Safeguards with Third-Party AI Vendors
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-03-C01 | Include enhanced AI-specific clauses in all third-party AI vendor contracts. | Procurement + GRC | Require bias audit reports, right-to-audit, sub-processor approval, and breach notification. | OSFI B-10 + GOVERN 6 |
| RA-03-C02 | Maintain a central inventory of all third-party AI models and components. | GRC | Update register for any new or changed vendor relationships. | MANAGE 3.1 |
| RA-03-C03 | Conduct ongoing monitoring and periodic re-assessment of third-party AI vendors. | GRC + Model Risk | Perform quarterly reviews and triggered re-assessments. | MANAGE 3.2 |
| RA-03-C04 | Where audit rights or vendor-log export cannot be negotiated, GRC shall document the residual gap and apply compensating controls. | GRC + Procurement | Record the vendor refusal in the TPRM file. Compensating controls include segmented access, less live credit data in Phase 1, more frequent reviews, cyber insurance, and termination rights. | OSFI B-10 (risk-based oversight); GOVERN 6 |
| RA-03-C05 | If the AI vendor or model is unavailable, automated credit shall refer or decline. It shall not fail open. | Credit Operations + IT | If the model or bureau call does not return an answer, or returns an error, the decision service refers or decline. It does not approve. Test this path before go-live and after vendor changes. | OSFI E-23; MANAGE 1.3 / 4.1 |
Key Controls for RA-04: Expanded Attack Surface from Open Banking APIs
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-04-C01 | Implement strong API security controls (authentication, rate limiting, encryption). | InfoSec | Apply OAuth 2.0 / mTLS and continuous monitoring. | NIST SP 800-53 AC-2, AC-3, SC-8 |
| RA-04-C02 | Conduct regular API security testing and vulnerability assessments. | InfoSec | Perform penetration testing and automated API scanning. | NIST SP 800-53 CA-2, RA-5 |
| RA-04-C03 | Open-banking sharing shall be limited to the scopes the customer authorized. Extra fields shall not be sent because a partner or model “might need them.” | Privacy + API/Open Banking owner | Enforce scope checks at the API gateway. Review partner payloads against the consent record | PIPEDA Principles 3 and 4; NIST SP 800-53 AC-3 |
Key Controls for RA-05: Legacy Mainframe Logging Gaps
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-05-C01 | Enhance logging and audit trail capabilities for systems feeding the AI platform. | IT / InfoSec | Implement centralized, tamper-proof logging. | NIST SP 800-53 AU-2, AU-3, AU-6 |
| RA-05-C02 | Perform periodic reviews of audit logs for AI-related data flows. | Internal Audit | Include AI data flows in regular audit scope. | NIST SP 800-53 AU-6 |
| RA-05-C03 | If the model, vendor, or a required feed is unavailable, automated credit shall refer or decline. It shall not fail open. | Credit Operations + IT | Same fail-closed default as RA-03-C05, including when a required legacy feed does not return an answer. | OSFI E-23; NIST SP 800-53 CP-2 / SI-4 |
| RA-05-C04 | Each in-scope AI shall have a rebuildable decision record: Decision ID, time, model version, input used, output and reason codes, any human override, and a vendor call ID when a third party scored it. Chain-of-thought text is not the record. | IT/Data Science + Model Risk | Write the record in the decision service (or audit topic), not in email or Excel. Phase 1 manual fallback must create the same record. | NIST SP 800-53 AU-2 / AU-3; OSFI E-23 |
Key Controls for RA-06: Inadequate Data Minimization in AI Models
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-06-C01 | Enforce data minimization principles in all AI model development and training. | Privacy + Data Science | Define and document data minimization rules per model. | PIPEDA Principle 4 (Limiting Collection) |
| RA-06-C02 | Conduct regular data minimization reviews for existing AI models. | Privacy | Review data usage in AI models at least annually. | PIPEDA Principle 5 (Limiting Use, Disclosure, and Retention) |
Key Controls for RA-07: Cross-Border Data Transfers to U.S.
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-07-C01 | Ensure appropriate safeguards for cross-border data transfers (e.g., SCCs). | Privacy + Legal | Maintain valid transfer mechanisms and documentation. | PIPEDA Principle 7 (Safeguards) |
| RA-07-C02 | Perform periodic assessments of cross-border data transfer risks. | Privacy | Review U.S. data flows and safeguards at least annually. | PIPEDA Principle 7 |
Key Controls for RA-08: Model Drift in Production AI Systems
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-08-C01 | Implement automated model drift detection for all production AI models. | Model Risk Management | Use statistical tests (e.g., KS test, PSI) with defined thresholds. | MEASURE 2.3 + MANAGE 2.2 |
| RA-08-C02 | Conduct periodic re-validation of production models. | Model Risk Management | Re-validate quarterly or upon material changes. | MANAGE 2.3 |
| RA-08-C03 | Define and document model retirement and replacement criteria. | Model Risk Management | Maintain fallback options and retirement process. | MANAGE 4.2 |
Key Controls for RA-09: Unsuitable or Uneven Product Recommendations
| Control ID | Control Description | Owner | Implementation Approach | Specific Reference |
|---|---|---|---|---|
| RA-09-C01 | Recommendation offers shall be logged, with an opt-out, and sampled for poor fit and uneven treatment across customers. | Product + Compliance | Log the product shown, the reason code, and the customer segment. Review a monthly sample. Compare offer rates for similar customers. Do not treat a recommendation as a credit decision. | FCAC fair treatment; PIPEDA Principle 3 |
| RA-09-C02 | A complaint that a recommendation was the wrong product shall be tied to a recommendation ID and routed to human review. | Compliance + Product | Reuse the case system. Store the recommendation ID on the complaint. Review within the bank’s complaint-handling timeline. | FCAC Complaint handling |
7. Monitoring, Testing & Audit Readiness
7.1 What This Section Covers
Controls on paper do not tell the bank whether the platform is behaving as approved. This section is how I check that after go-live.
There are three related activities.
Monitoring is the regular view of live activity. I look at a small set of signals – consent and retention, whether automated credit stays inside the Phase 1 group, vendor calls that do not return an answer, open-banking scopes, missing decision records, and drift on credit and fraud. Each signal has an owner, a place the evidence is stored, and a response when it breaks.
Testing is a scheduled check that a few high-harm paths still work. The important ones for this platform are: automated approval cannot run for customers outside the Phase 1 group; if the model or a required vendor call does not return an answer, credit is referred or declined rather than approved; and a complaint can be rebuilt from a Decision ID.
Audit readiness is the ability to pull that evidence in a straight line when internal audit or reviewer asks about this platform. The keys are Decision ID, consent record, and vendor ID. This is readiness for this initiative under bank’s policies, PIPEDA, and OSFI/FCAC-style expectations. It is not a claim that the same folder is an ISO 27001 or ISO 42001 certification file. Readers who want a sample folder index can use a downloadable pack, the same way the updated policies sit as PDFs.
Phase 1 has to be enforced in the decision service, not only described in the project plan. Shadow mode (same-engine shadow) means the model may score live applications, but that score must not post a credit limit. A low-amount cohort means only those applications may auto-approve. Bypass happens when another channel – a batch job, staff tool, a vendor callback, or a wrong flag – posts an approval for someone outside that group. Monitoring counts those posts. Testing tries to create one on purpose and confirms it is blocked.
7.2 Monitoring Map
| Family | Linked Risks | What We Watch | Where the Evidence Sits | Owner | Frequency | Trigger |
|---|---|---|---|---|---|---|
| Consent and personalization | RA-01, RA-06 | Share of customers in Basic vs Full Mode; profiling without a recorded opt-in; profile age vs retention rule | Consent platform + profile store | Privacy/GRC | Weekly in Phase 1, then monthly | Full Mode rising without opt-in, or profiles kept past the deletion rule -> pause new profiling features |
| Credit fairness and Phase 1 limits | RA-02 | Cohort boundary (shadow / low-amount only); fairness metrics on the live cohort; human review rate; kill-switch readiness | Decision service + Model Risk file | Model Risk + Credit ops | Daily exception review in Phase 1; formal fairness pack before any cohort expansion | Decision outside approved cohort, or fairness breach -> kill switch and no expansion |
| Consumer handling of automated credit | RA-02 | Complaint volume tagged with Decision ID; time to human review; disclosure shown at decision | Case system | Compliance + Credit Ops | Weekly | Complaint has no Decision ID, or human review is later than the stated timeline (for example 10 business days) -> treat as a control failure, not only a customer-service issue |
| AI vendors | RA-03 | Contractual gaps on file; how often a bureau or fraud-signal call does not return an answer; how much live credit data the vendor still receives in Phase 1 | TPRM register + decision logs | GRC + Procurement | Monthly, and on incident | A required vendor call does not return an answer, a breach notice arrives, or the vendor receives more live credit data than Phase 1 allows -> fail-closed credit and re-tier the vendor |
| Open banking APIs | RA-04 | Authentication failures; abnormal call volume; calls from a new app, and whether the data fields sent match what the customer allowed. | API gateway + SIEM | InfoSec + Open Banking owner | Continuous alerts; weekly review | Extra fields in the message, a sharp rise in calls, or calls from an app that was not approved -> block that permission or that partner |
| Decision records and hops | RA-05 | Completeness of Decision ID, model version, inputs, output, override, vendor call ID; leftover Excel/SFTP/email hops | Decision log | IT + Model Risk | Daily completeness check in Phase 1; sample weekly after | Missing record or unlogged override -> stop using that hop for live credit |
| Cross-border transfers | RA-07 | Whether U.S. flows still match the approved mechanism (SCC/localization) | Privacy/legal file + data-flow inventory | Privacy + Legal | Quarterly, and on vendor or architecture change | New U.S. hop not on the map -> pause that flow |
| Drift after go-live | RA-08 | Performance and fairness drift on credit and fraud first; recommendation quality second | Model monitoring dashboard | Model Risk | Automated alerts; credit/fraud reviewed faster than recommendations | Credit/fraud drift alert -> human fallback and hold retraining approval |
| Recommendation quality | RA-09 | Share of “wrong product/not helpful” complaints; offer rates for similar customers; opt-out use | Recommendation log + case system | Product + Compliance | Monthly sample | Similar customers see very different offers, or complaints have no recommendation ID -> pause that offer type |
7.3 Testing
Testing checks that a high-harm control still does what it says. It gives the bank evidence that the control operated, and it gives internal audit something to sample or re-perform. It is not a second copy of the monitoring map, and it is not a script for every control.
High-harm here means the register rows rated Critical or High. Medium rows are included only where a sample is already a part of the control.
I use two methods.
Try to break the rule. I set up a known case, run it in a test environment or as a marked synthetic transaction, and compare the result with what the control requires. The input, the result, and the owner are filed so a reviewer can see the test without re-running it.
Rebuild a real record. I take a live complaint, a vendor file, or a sampled decision and follow the ID. If a hop has no record, the evidence path failed, even if a dashboard was green.
Technical tests are run by the first line. I define the expected result and review the evidence. I do not personally inject the drift file or stop the bureau call.
| Layer | Who | What they do |
|---|---|---|
| First line | Data science, Model Risk engineering, IT, Credit Ops, InfoSec | Run the monitor, inject the test, hold posting, fix the feed |
| Second line | GRC, Privacy, Model Risk oversight | Say what must be tested, review the evidence, challenge a pass that has no file |
| Third line | Internal audit | Sample or re-perform a few tests |
Method 1: Try to break the rule
| Check | What you try | Risk |
|---|---|---|
| Consent default | Open a new profile with no separate opt-in and see if full profiling is on | RA-01 |
| No answer | Stop the bureau or model from answering and see if credit still approves | RA-03, RA-05 |
| Phase 1 boundary | Submit an application outside the approved group and see if a limit posts | RA-02 |
| Open-banking fields | Send a field the customer did not allow | RA-04 |
| Retention | Confirm a profile past the deletion rule is actually removed | RA-06 |
Method 2: Rebuild a real record
| Check | What you pull | Risk |
|---|---|---|
| Vendor gap | Vendor file -> refused log rights and the compensating controls | RA-03 |
| Credit complaint | Case ticket -> Decision ID -> version, inputs, output, override | RA-02, RA-05 |
| Life fairness pack | The fairness result on the live cohort, not only the pre-launch file | RA-02, RA-08 |
| Life fairness pack | The fairness result on the live cohort, not only the pre-launch file | RA-02, RA-08 |
| Retention | Confirm a profile past the deletion rule is actually removed | RA-06 |
| Drift alert | One credit drift alert -> who reviewed it, and whether posting was held | RA-08 |
| Recommendation complaint | Case ticket -> recommendation ID | RA-09 |
RA – 07 is a file review, not a break-the-rule test: confirm the transfer map still matches the approved mechanism. RA-09 is Medium. It stays on the map because the control already calls for a complaint sample.
A Worked Example of How a Test Is Done: No Answer Must Not Approve (RA-03-C05 and RA-05-C03)
One test covers both control. RA-03-C05 is the vendor or model call. RA-05-C03 is the same rule when a required feed does not return.
- Use a credit application that is inside the approved Phase 1 group, so it would be allowed to post if a score comes back.
- Stop the bureau or the model from returning an answer.
- Submit an application through the decision service.
- Expected result: refer or decline, a Decision ID written, no limit posted.
- An approval with no score is a fail.
- Store the input, the result, and the tester against RA-03-C05 and RA-05-C03
A real credit complaint uses the second method. Start from the case ticket, follow the Decision ID, and stop if a hop has no record.
7.4 Audit File
Audit readiness here means a reviewer can get from a question to the evidence without a scavenger hunt. It is for this platform, under the bank’s policies, PIPEDA, and OSFI/FCAC-style expectations. It is not an ISO 27001 or ISO 42001 certification file.
I keep three references. A credit complaint uses the Decision ID. A profiling question uses the consent record. A vendor question uses the vendor ID. If those references are missing, the evidence cannot be tied together.
| Audit request | Evidence | Source system | Reference |
|---|---|---|---|
| Why was this credit outcome issued? | Decision log extract | Case system + decision log | Decision ID |
| Was Phase 1 bypassed? | Cohort flag on that decision | Decision service | Decision ID |
| What did we do when the vendor would not share logs? | Gap memo and compensating controls | TPRM file | Vendor ID |
| Was full profiling opted in? | Consent record | Consent platform | Customer and consent record |
| What happened when the model or bureau did not answer? | Filed test result | Test record | RA-03-C05 and RA-05-C03 |
A separate walkthrough shows how I prepare one credit complaint so a reviewer can follow it: Decision ID on the ticket, matching row in the decision log, built in a free ServiceNow developer instance. I also show the self-check I would do before the audit asks – if the ID does not tie the two records together, the file is not ready. It is not an audit, and it is not an ISO certification. Link:[to be added]